
 Staff Research Scientist, Xiaomi Robotics
Hi, I'm Yiran. I am a Staff Research Scientist at Xiaomi Robotics, where I lead research on closed-loop evaluation and self-evolving embodied intelligence. My research focuses on developing scalable agentic policies, evaluation frameworks, autonomous improvement mechanisms, and data-driven approaches for next-generation robotic systems.
I am hiring research interns at Xiaomi Robotics! I am excited to work with people who share the ambition to scale embodied intelligence and turn exploratory ideas into real systems. If you are interested in embodied agents, closed-loop evaluation, or self-evolving robot learning, please feel free to email me with your CV.
Previously, I was the Director of Data and Algorithm at NeoteAI, where I built a large-scale, tactile-enabled embodied data infrastructure spanning five robot embodiments and the tactile handheld N0-TacUMI, and served as technical lead of the N0 series of tactile-native foundation models pretrained on more than 30,000 hours of self-collected data. I received my Ph.D. from The Chinese University of Hong Kong, Shenzhen in July 2026, advised by Prof. Ruimao Zhang, and was a visiting researcher at TVG, University of Oxford, advised by Prof. Philip Torr. I also interned at Shanghai AI Laboratory, Kuaishou Kling, and NIO, and have had the honor of collaborating with Prof. Lei Bai, Prof. Xihui Liu, Dr. Xintao Wang, and my friend Jiwen Yu.

Warning
Problem: The current name of your GitHub Pages repository ("Solution: Please consider renaming the repository to "
http://".
However, if the current repository name is intended, you can ignore this message by removing "{% include widgets/debug_repo_name.html %}" in index.html.
Action required
Problem: The current root path of this site is "baseurl ("_config.yml.
Solution: Please set the
baseurl in _config.yml to "Education
-
 TVG, Oxford UniversityVisiting ResearcherJul. 2025 - Aug. 2026
-
 The Chinese University of Hong Kong, ShenzhenPh.D.Sep. 2021 - Jul. 2026
-
 The University of Hong KongVisiting Ph.D. StudentMar. 2024 - Jul. 2025
-
 Shandong UniversityB.S. in Computer ScienceSep. 2017 - Jul. 2021
Experience
-
Xiaomi RoboticsStaff Research ScientistSep. 2026 - present
-
 NeoteAIDirector of Data and AlgorithmJan. 2026 - Aug. 2026
-
 Shanghai AI LaboratoryResearch Intern, advised by Dr. Lei BaiApr. 2025 - Jan. 2026
-
 Kuaishou KlingResearch Intern, advised by Dr. Xintao WangOct. 2024 - Apr. 2025
-
Shanghai AI LaboratoryResearch Intern, advised by Dr. Jing ShaoJun. 2023 - Oct. 2024
-
 NIOResearch Intern, advised by Dr. Ningning MaDec. 2021 - Jun. 2023
News
Selected Publications (view all )

N₀-Foundation: Towards the Age of Tactile Intelligence
Yiran Qin (Technical Lead), NeoteAI Team, Fudan TEAI Team
Technical Report 2026
A tactile-centric foundation for embodied manipulation that unifies scalable tactile hardware, 30,000+ hours of multimodal data across six embodiments, transferable tactile representations, and standardized real-world and simulated benchmarks.

N₀-VTLA: Scaling Vision-Tactile-Language-Action Model with Latent Tactile Tokens
Yiran Qin (Technical Lead), NeoteAI Team, Fudan TEAI Team
Technical Report 2026
A vision-tactile-language-action foundation model for contact-rich manipulation that predicts future tactile tokens and improves offline from demonstrations, failures, human corrections, and recoveries.

N₀-TWAM: Scaling Tactile-Native World Action Model for Contact-Rich Manipulation
Yiran Qin (Technical Lead), NeoteAI Team, Fudan TEAI Team
Technical Report 2026
A tactile-native world-action model that jointly predicts future vision, touch, and action, combining anticipatory and observed tactile pathways for contact-rich manipulation.
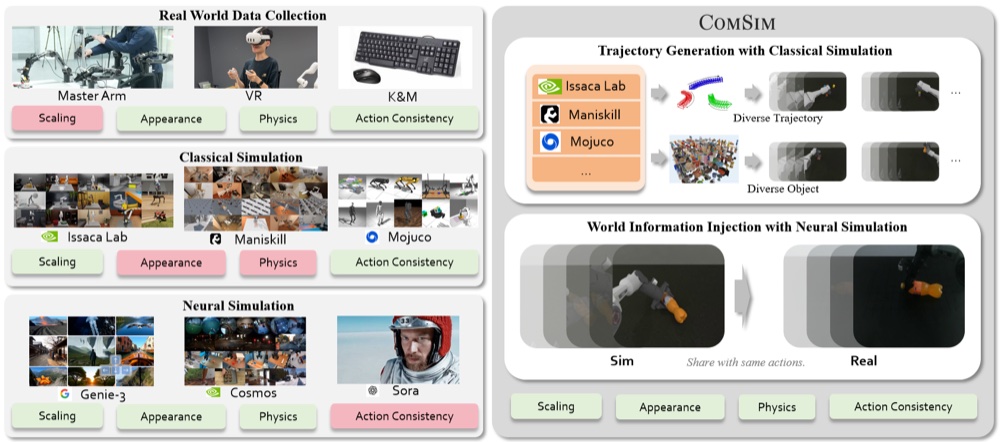
ComSim: Building Scalable Real-World Robot Data Generation via Compositional Simulation
Yiran Qin*, Jiahua Ma*, Li Kang*, Wenzhan Li*, Yihang Jiao, Xin Wen, Xiufeng Song, Heng Zhou, Zhemeng Zhang, Zhenfei Yin, Xihui Liu, Philip Torr, Ruimao Zhang#(* equal contribution, # corresponding author)
Conference on Robot Learning (CoRL) 2026

CDP: Towards Robust Autoregressive Visuomotor Policy Learning via Causal Diffusion
Jiahua Ma*, Yiran Qin*†, Yixiong Li, Xuanqi Liao, Yulan Guo, Ruimao Zhang#(* equal contribution, # corresponding author, † project lead)
Conference on Robot Learning (CoRL) 2025
CDP: Towards Robust Autoregressive Visuomotor Policy Learning via Causal Diffusion
Jiahua Ma*, Yiran Qin*†, Yixiong Li, Xuanqi Liao, Yulan Guo, Ruimao Zhang#(* equal contribution, # corresponding author, † project lead)
Conference on Robot Learning (CoRL) 2025

VIKI-R: Coordinating Embodied Multi-Agent Cooperation via Reinforcement Learning
Li Kang*, Xiufeng Song*, Heng Zhou*, Yiran Qin#, Jie Yang, Xiaohong Liu, Philip Torr, Lei Bai#, Zhenfei Yin#(* equal contribution, # corresponding author)
Annual Conference on Neural Information Processing Systems (NeurIPS) 2025

Context as Memory: Scene-Consistent Interactive Long Video Generation with Memory Retrieval
Jiwen Yu, Jianhong Bai, Yiran Qin, Quande Liu#, Xintao Wang, Pengfei Wan, Di Zhang, Xihui Liu#(# corresponding author)
SIGGRAPH Asia 2025
Context as Memory: Scene-Consistent Interactive Long Video Generation with Memory Retrieval
Jiwen Yu, Jianhong Bai, Yiran Qin, Quande Liu#, Xintao Wang, Pengfei Wan, Di Zhang, Xihui Liu#(# corresponding author)
SIGGRAPH Asia 2025

RoboFactory: Exploring Embodied Agent Collaboration with Compositional Constraints
Yiran Qin*, Li Kang*, Xiufeng Song*, Zhenfei Yin#, Xiaohong Liu, Xihui Liu, Ruimao Zhang#, Lei Bai#(* equal contribution, # corresponding author)
International Conference on Computer Vision (ICCV) 2025 Best Paper Award at CVPR 2025 MEIS Workshop

GameFactory: Creating New Games with Generative Interactive Videos
Jiwen Yu*, Yiran Qin*, Xintao Wang#, Pengfei Wan, Di Zhang, Xihui Liu#(* equal contribution, # corresponding author)
International Conference on Computer Vision (ICCV) 2025 Highlight
GameFactory: Creating New Games with Generative Interactive Videos
Jiwen Yu*, Yiran Qin*, Xintao Wang#, Pengfei Wan, Di Zhang, Xihui Liu#(* equal contribution, # corresponding author)
International Conference on Computer Vision (ICCV) 2025 Highlight

Interactive Generative Video as Next-Generation Game Engine
Jiwen Yu*, Yiran Qin*, Haoxuan Che, Quande Liu, Xintao Wang#, Pengfei Wan, Di Zhang, Xihui Liu#(* equal contribution, # corresponding author)
ArXiv Preprint
Interactive Generative Video as Next-Generation Game Engine
Jiwen Yu*, Yiran Qin*, Haoxuan Che, Quande Liu, Xintao Wang#, Pengfei Wan, Di Zhang, Xihui Liu#(* equal contribution, # corresponding author)
ArXiv Preprint

WorldSimBench: Towards Video Generation Models as World Simulators
Yiran Qin*, Zhelun Shi*, Jiwen Yu, Xijun Wang, Enshen Zhou, Lijun Li, Zhenfei Yin, Xihui Liu, Lu Sheng, Jing Shao#, Lei Bai#, Ruimao Zhang#(* equal contribution, # corresponding author)
International Conference on Machine Learning (ICML) 2025 Oral at CVPR 2025 WorldModelBench Workshop

NavigateDiff: Visual Predictors are Zero-Shot Navigation Assistants
Yiran Qin*, Ao Sun*, Yuze Hong, Benyou Wang, Ruimao Zhang#(* equal contribution, # corresponding author)
International Conference on Robotics and Automation (ICRA) 2025
NavigateDiff: Visual Predictors are Zero-Shot Navigation Assistants
Yiran Qin*, Ao Sun*, Yuze Hong, Benyou Wang, Ruimao Zhang#(* equal contribution, # corresponding author)
International Conference on Robotics and Automation (ICRA) 2025

Minedreamer: Learning to follow instructions via chain-of-imagination for simulated-world control
Enshen Zhou*, Yiran Qin*, Zhenfei Yin†, Yuzhou Huang, Ruimao Zhang#, Lu Sheng#, Yu Qiao, Jing Shao(* equal contribution, # corresponding author, † project lead)
International Conference on Intelligent Robots and Systems (IROS) 2025

Mp5: A multi-modal open-ended embodied system in minecraft via active perception
Yiran Qin*, Enshen Zhou*, Qichang Liu*, Zhenfei Yin, Lu Sheng#, Ruimao Zhang#, Yu Qiao, Jing Shao†(* equal contribution, # corresponding author, † project lead)
Conference on Computer Vision and Pattern Recognition (CVPR) 2024
